Amazon Ads Agent post-training its LLMs
Amazon's AI agent for advertisers: describe a goal in plain language, and it plans, launches, optimizes, and measures the campaigns.
- In production
 Wenbo ChenLLM agents: post-training, evaluation & infra
Making LLM agents better, and proving they really are.
I'm a researcher at Amazon, post-training the LLMs behind Amazon Ads Agent. I work on LLM agents end to end: post-training the model, building the benchmarks that measure it, and the infrastructure that makes training fast and grading honest.
ML PhD from Georgia Tech / NSF AI4OPT with Pascal Van Hentenryck, where my work on scalable data-driven decision making saw major industrial adoption.
What I work on
A better agent needs a benchmark that can tell it is better, and infrastructure fast enough to try again. I work on all three, and every piece ships with a check.
Amazon's AI agent for advertisers: describe a goal in plain language, and it plans, launches, optimizes, and measures the campaigns.
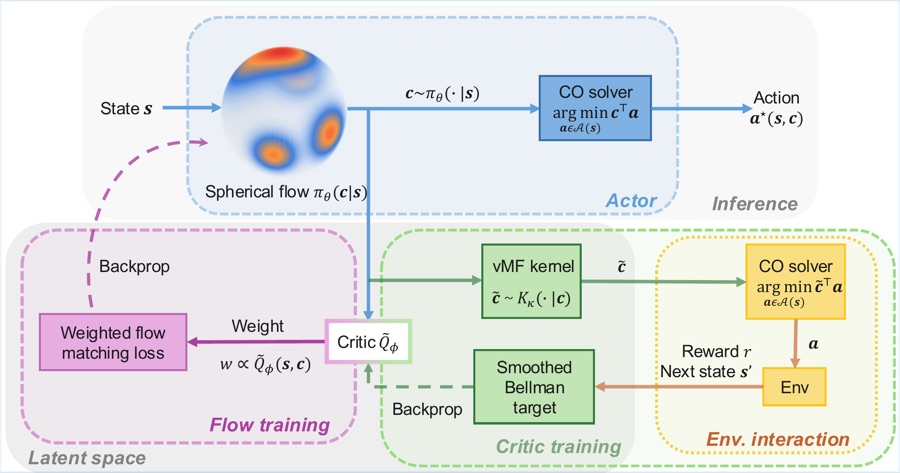
RL where every move combines many choices, with a solver that keeps every move valid: +20.6% over the prior best.
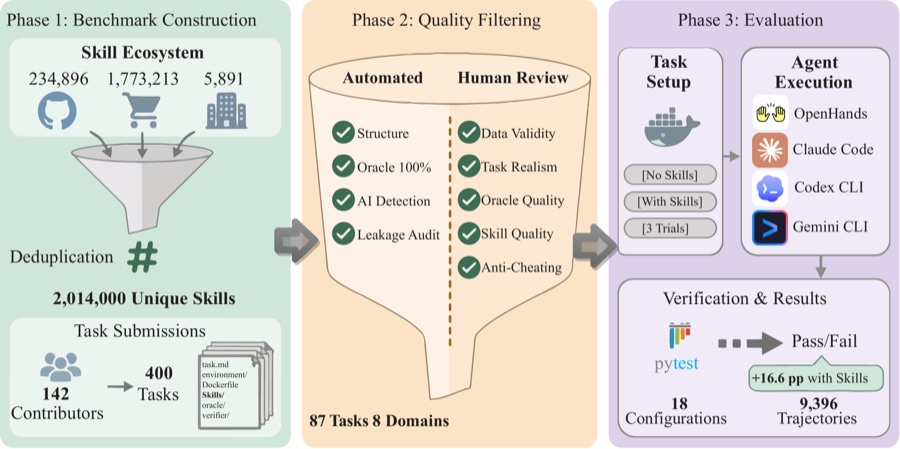
Do skills actually help AI agents? 87 expert tasks with exact checkers: curated skills add 16.6 points.
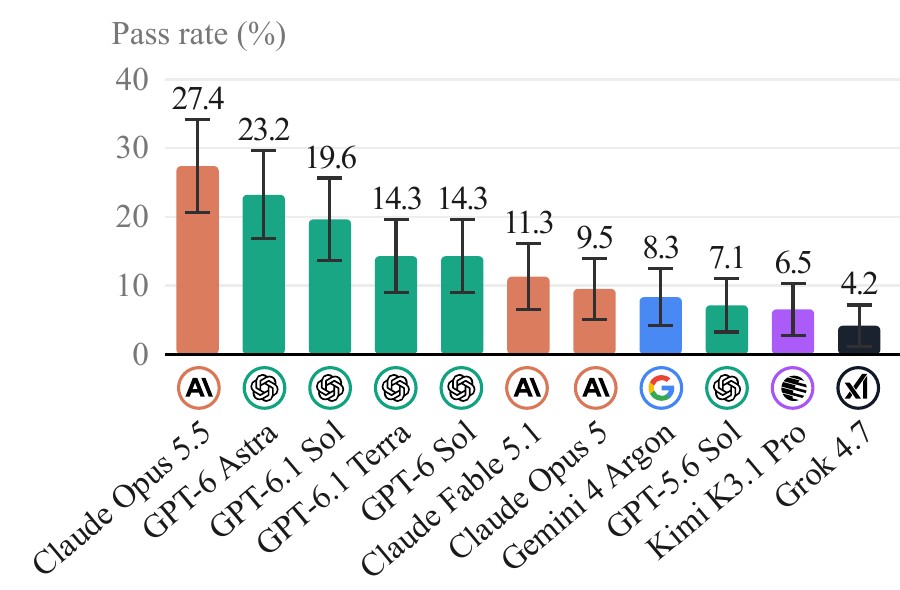
Can agents do real physics research? 56 tasks from 42 physicists' own projects: the best agent passes 27.4%.
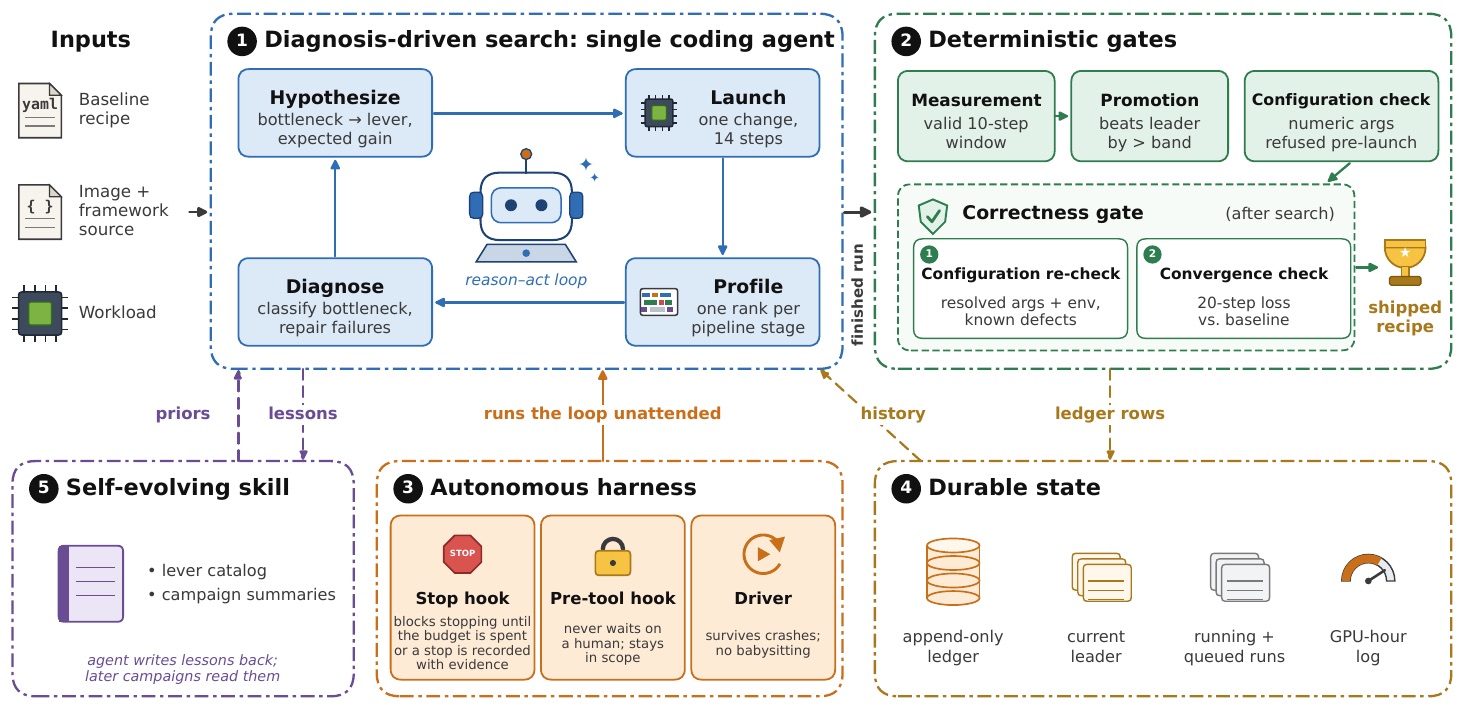
A coding agent tunes LLM training on its own, and a correctness gate checks every change: 1.7× throughput over expert recipes.
Latest